← Back to product matrixDigital Human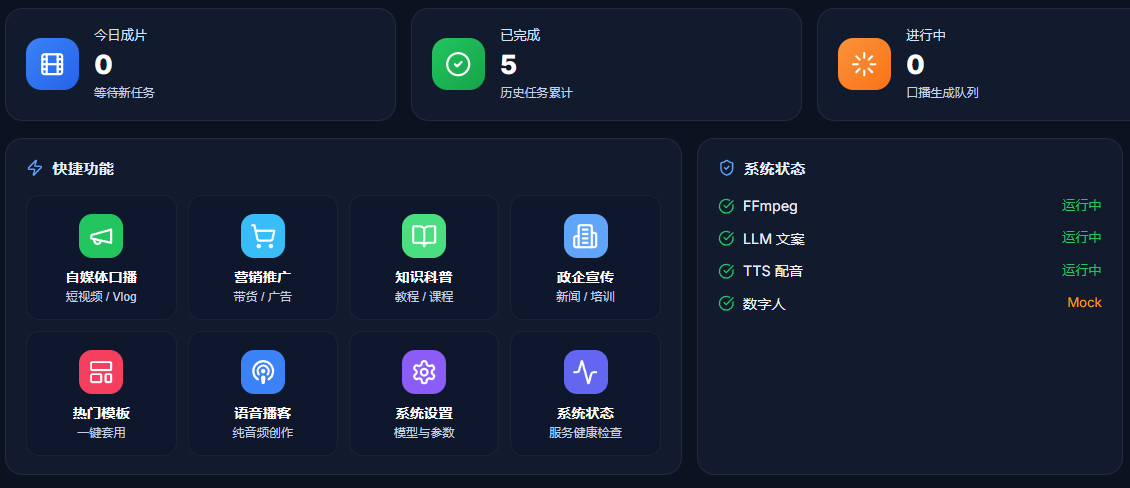
Digital Human
Real-person likeness cloning + lip-sync driving — explainer videos in batches.
Di// MEDIA COMING SOON
Train the likeness once from a piece of real footage; after that, feed any text and it renders an explainer video with matching mouth movement and natural expression. Voiceover rides the TTS pipeline so voices stay reusable; rendering is queued, so a dozen scripts can produce a dozen videos in one batch. Great for courses, product explainers and talking-head channels.
- Likeness captured once, reused long-term — no repeated filming
- Lips aligned with the voiceover; mixed Chinese-English reading supported
- Batch tasks queue up: swap the script and produce another batch
MORE
More to explore
AI Tools
EnlyAI Voice Station
A locally-running voice transcription and dubbing workstation — voices never leave your intranet.
EnlyAI Voice Station→
Automation
Xianyu Butler
Multi-account Xianyu operations hub: auto-replies, product patrols and order alerts.
Xianyu Butler→
Automation
Content Factory
Trend capture → AI rewriting → scheduled publishing across platforms — topics never run dry.
Content Factory→